Data Infrastructure in Healthcare: Scaling HL7, Kafka Pipelines & Eliminating Data Bottlenecks
By 110 AI & Automation Technologies
Healthcare is no longer just about patient care -- it's about data at scale. From electronic health records (EHRs) to AI-driven diagnostics, modern healthcare systems depend on high-throughput, low-latency, and reliable data infrastructure. But with increasing complexity comes a critical challenge: how do you keep healthcare data flowing seamlessly without choking the system?
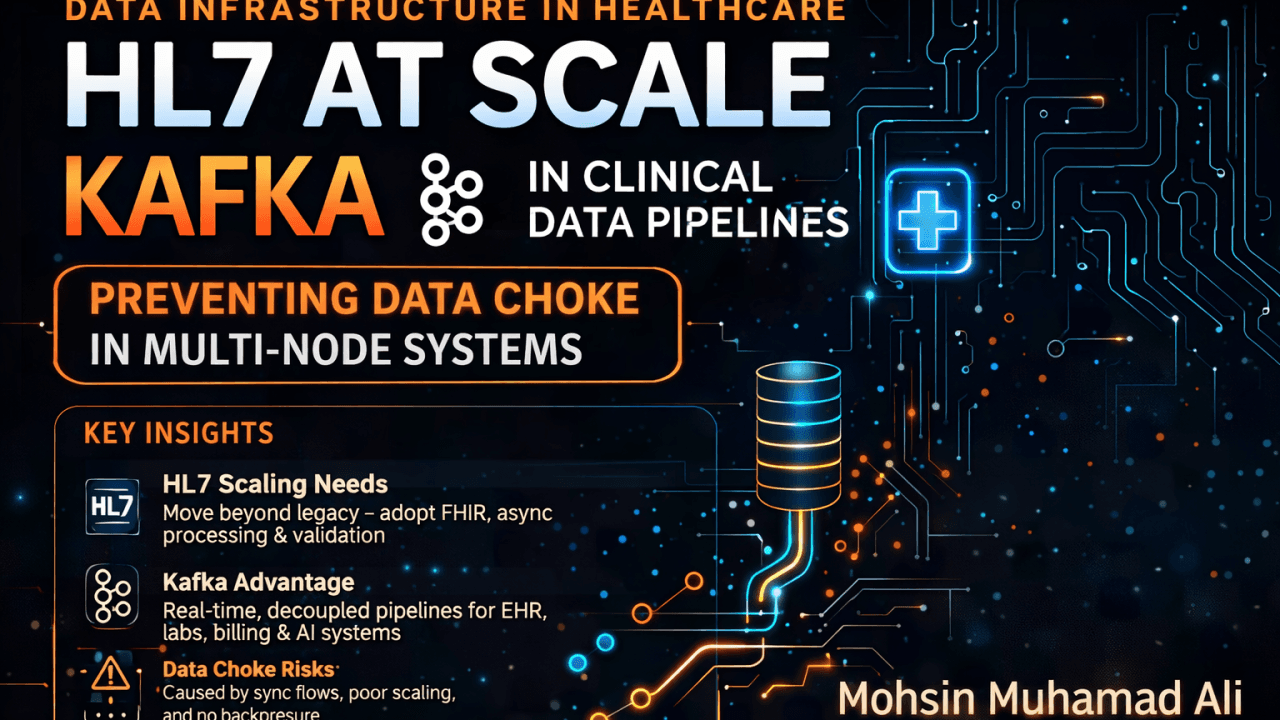
This article looks at three connected pieces of that puzzle: scaling HL7 messaging, using Kafka in clinical data pipelines, and preventing data choke in distributed systems.
HL7 at Scale: The Backbone Under Pressure
HL7 (Health Level Seven) has long been the standard for healthcare data exchange. But scaling HL7 is not trivial.
The Problem
Traditional HL7 implementations were designed for point-to-point communication and low-to-moderate message volumes. Today's reality looks different: millions of messages a day, and real-time integrations across labs, pharmacies, insurance systems, and AI models.
Common Issues at Scale
- Message queue overload
- Parsing latency
- Duplicate or out-of-order messages
- Interface engine bottlenecks
Modern Solutions
- Use interface engines built for horizontal scaling
- Implement message validation and schema enforcement early
- Adopt FHIR (Fast Healthcare Interoperability Resources) where possible
- Introduce asynchronous processing instead of synchronous flows
Key insight: HL7 isn't the problem -- legacy architecture is.
Kafka in Clinical Data Pipelines: The Game Changer
Apache Kafka has become the central nervous system for real-time healthcare data streaming.
Why Kafka Works in Healthcare
Kafka provides high throughput (millions of events per second), fault tolerance, real-time streaming, and a decoupled architecture -- exactly what interconnected clinical systems need.
A typical flow looks like this: EHR System → HL7 Messages → Kafka Producer → Kafka Topics → Consumers (Billing, Analytics, AI Models).
Benefits in Clinical Systems
- Eliminates tight coupling between systems
- Enables real-time patient monitoring
- Supports event-driven architecture
- Improves scalability across departments
Challenges to Watch
- Schema evolution issues (HL7 to JSON/Avro)
- Message ordering in critical workflows
- Data consistency across consumers
- Regulatory compliance (HIPAA, PHI handling)
Best Practices
- Use a Schema Registry (Avro/Protobuf)
- Implement topic partitioning carefully
- Ensure idempotent consumers
- Apply data encryption and masking
Key insight: Kafka doesn't just move data -- it unlocks real-time healthcare intelligence.
Preventing Data Choke in Multi-Node Systems
As healthcare systems evolve into distributed architectures, data choke becomes inevitable unless it's proactively handled.
What Is Data Choke?
A situation where data inflow exceeds processing capacity, nodes become overloaded, and system latency spikes or crashes.
Common Causes
- Poor load balancing
- Synchronous dependencies
- Inefficient database queries
- Lack of backpressure handling
Strategies to Prevent It
- Backpressure mechanisms -- control data flow between producers and consumers to prevent system overload.
- Horizontal scaling -- add more processing nodes dynamically, using container orchestration like Kubernetes.
- Async processing -- replace blocking operations with event-driven workflows.
- Smart queueing -- use Kafka or RabbitMQ to buffer spikes.
- Observability -- real-time monitoring (Prometheus, Grafana) with alerting on latency, throughput, and failures.
- Circuit breakers -- prevent cascading failures across services.
Key insight: Data choke is not a failure -- it's a design flaw.
Final Thoughts
Healthcare data infrastructure is entering a new era. HL7 must evolve beyond legacy constraints, Kafka enables real-time and scalable pipelines, and distributed systems demand proactive choke prevention.
The real differentiator is no longer just data availability -- it's data reliability, speed, and resilience at scale.